Alex Stamos Has to Turn AI Bug Hunts Into Fixes
On this page 8 sections
AI-generated editorial illustration.
On October 26, Cognition described a security product that can do more than report a software vulnerability. Its upgraded Devin Security would investigate a finding against a customer’s own systems, reproduce a flaw, propose a fix, run tests and open a pull request. It could also recommend that a security team accept a lower risk rating or apply a temporary network control while a permanent repair waits. Two days later, the founders of security startup Corridor announced that their company was joining Cognition to work on Devin Security. They named Alex Stamos, Cognition’s new security chief, as someone they would work with again.
Those announcements put a familiar security problem under a new deadline. More powerful AI can search for flaws in large codebases. A defender may receive a longer list, and an attacker may search the same code. A discovered flaw is not a repaired one. Even a merged patch is not proof that the vulnerable service has been updated. Cognition’s product account addresses the whole path, from discovery to a tested change. It does not publish a customer cohort showing how many findings became deployed, durable fixes or how long each stage took.
Stamos has been arguing that this missing interval is becoming the important measure. In a readable October 30 interview with The Atlantic, he said that faster bug finding should push defenders beyond repeated emergency patches toward rewriting unsafe code and lowering the cost of defense. That is his assessment of a fast-moving threat, not an independent count of attacks caused by AI. At Cognition, it also becomes a product test. Can a company that sells coding agents shorten the time during which a real customer remains exposed, without letting an unreviewed agent decide that a plausible-looking patch is safe?
The security chief who came to build
Axios reported on September 29 that Stamos had joined Cognition as chief security officer. He told the publication he intended to protect the company and help ship security products. Axios also reported his interest in tools that could rewrite older enterprise software into more modern architectures. That was a stated plan at the time of his hiring. The October 26 Devin Security release supplies a more concrete product to assess, though Cognition describes it as a team effort and does not assign every design decision to him.
The October 26 release says a customer can give Devin a threat model covering services, network policies, deployment paths and business impact. The system can then use frontier cyber models to investigate findings, run reproduction tests in separate virtual machines and prepare changes for engineers to review. The Corridor announcement came from its co-founders Jack Cable and Ashwin Ramaswami. They said they were joining Cognition to expand that security work and named Stamos, President Russell Kaplan and CTO Steven Hao among the people involved. The announcement establishes a team and a direction. It does not establish which individual designed a feature, an acquisition price or an improved customer outcome.
Stamos’s job is unusually exposed because he sits on both sides of a sale. A security chief must judge the controls protecting Cognition’s own products and customers. A product leader must argue that those controls can work for other companies. The same question applies in each place: how does a team distinguish an urgent, exploitable weakness from a scanner’s false alarm, and how does it know that the chosen repair has actually removed the weakness?
The company has a practical reason to make that distinction visible. Security teams already receive advisories, scanner alerts, bug reports and compliance deadlines. More detection can consume the engineers needed to repair anything. Cognition’s release proposes a single queue that ingests existing findings as well as its own scans, deduplicates them and attaches evidence. That is a product design, not yet a public measure of effectiveness.
For a buyer, the strongest possible demo would have little to do with the number of vulnerabilities displayed on a dashboard. It would start with a disputed finding in the customer’s own code, show the route by which an attacker could reach it, demonstrate that the proposed fix blocks that route without breaking a service, and follow the change into production. A claim about thousands of parallel agent sessions answers only one part of that sequence.
A bigger search creates a repair queue
Stamos told The Atlantic that models capable of finding bugs can also help attackers automate more steps of an intrusion. He distinguished a disclosure wave from attacks he believes are occurring and argued that legacy code gives both sides a large supply of flaws to inspect. The interview is useful because it reveals the premise behind his product strategy. It is not a denominator for the number of AI-assisted incidents across the internet. A public list of striking cases cannot tell a reader how often a model caused exploitation, how often defenders found the flaw first, or whether the same organization would have been breached without it.
The repair problem exists even without that denominator. A vulnerability can be found in a library, in application logic or in the way several services interact. The relevant asset may not be exposed to the internet. A network rule may already block a path. Or a weakness may be reachable only through an account with privileges an attacker is unlikely to obtain. An engineer who fixes every theoretical flaw in score order can spend days on a low-risk service while a known exploited flaw waits. An engineer who dismisses too many findings can miss the one attack route that matters.
The US Cybersecurity and Infrastructure Security Agency maintains a Known Exploited Vulnerabilities catalog to identify flaws for which there is evidence of exploitation. A catalog entry gives defenders a powerful prioritization signal. It does not by itself reveal whether a given company’s copy of the affected software is exposed, whether a vendor patch has been installed, or whether another control already blocks the route. Cognition says Devin Security keeps a catalog-listed flaw from being relabeled as a lower-risk finding. That is a sensible constraint on a system that can otherwise propose risk adjustments. It still leaves the difficult work of finding the affected asset and confirming the repair.
A controlled training study offers a different warning. ITPro’s November 4 report described SecureFlag’s analysis of 805,663 attempts to fix flaws on its training platform over two years. About a quarter of attempts did not fully solve the exercise, according to the company. That is a training-platform result, not an estimate of real-world breaches and not a test of Devin Security. Its relevance is narrower: a fix can look credible to its author and still fail the exercise’s security condition. SecureFlag’s chief technology officer, Emilio Pinna, argued that a developer who cannot diagnose a flaw may also struggle to verify an AI-written repair. His company sells security training, so the interpretation deserves the same scrutiny as Cognition’s product claims.
The two accounts meet at the review desk. An agent can produce a patch faster than a human team can examine it. If the patch weakens an access check or covers one route while leaving another open, speed has shortened the writing stage and extended the exposure stage. Stamos’s argument depends on reducing that second stage. Counting pull requests cannot show it.
Mapping the customer’s actual exposure
In Cognition’s October release, the first step is a shared threat model, not a scan. The company says Devin maps systems, services, hosts, network policies and how code is deployed. A customer’s security and engineering teams add facts the code cannot provide: whether a service is internal, which region it runs in, which account types can reach it, and what damage would follow if one user could read another’s data. The model guides the scans and the ranking that follows.
Source code alone cannot say what a business considers a critical asset or whether an authentication gate is deployed in front of a service. A vulnerability scanner can flag a dangerous function in a repository that is never built. It can also overlook a business-logic flaw in a service whose individual components pass ordinary checks. Cognition’s proposed answer is to keep an explicit, changing description of the customer’s actual environment beside the code.
That description can be wrong. A deployment may move from an internal network to a public endpoint. A temporary exception may remain after a migration. A team might give Devin incomplete information about a privileged account. The product release says the threat model is living and expands as systems change. It does not publish the rate at which customers update that model or how often an outdated description changes a finding’s priority. A buyer has to ask who maintains it, which changes trigger re-evaluation and how conflicting human and agent observations are resolved.
The distinction between a severity label and a repair decision can be shown without a real customer’s private data. Imagine a library flaw that permits data access under one unusual configuration. If the affected version is not in production, the immediate repair may be a dependency cleanup. If it sits on a public service holding customer data, the same code path may demand containment before a full patch. If the service is internal but reachable through an overprivileged agent account, the access map becomes decisive. These are illustrative cases, not reported Cognition customer incidents. Their purpose is to show why a score by itself cannot choose the repair order.
Stamos’s earlier work gives this approach some context. Stanford’s institutional biography lists security leadership at Yahoo and Facebook, the founding of iSEC Partners and his later work at the Stanford Internet Observatory. Those roles span code-level security, giant platforms and public-accountability disputes. They do not prove that Cognition’s current threat models are accurate. They do help explain why his published interviews keep returning to the distance between finding a flaw and changing a large system safely.
One finding, several possible responses
Cognition describes four responses after a finding has been investigated. The choice is more consequential than merely moving a ticket to a new column.
| Proposed response in Cognition’s October release | What it can accomplish | What still needs proof |
|---|---|---|
| Document a false positive or risk adjustment | Free engineers from a finding that does not apply, while retaining the original score and an approval record. | The reachability evidence must be correct; a human must approve the proposed change, and known exploited entries cannot be relabeled. |
| Apply an infrastructure control | Restrict a path through a firewall rule, security-group change or access removal while a permanent patch waits. | The control must be deployed, tested and monitored; the underlying vulnerable code remains. |
| Fix the flaw | Reproduce it in an isolated virtual machine, change code, run reproduction and existing tests, then open a pull request. | A reviewer must assess the fix, the PR must merge and deploy, and the original exploit must remain blocked in production. |
| Refactor the vulnerability class | Replace a recurring unsafe pattern such as scattered authorization checks. | A larger change needs broader compatibility, regression and maintenance evidence than a single patch. |
These are the company’s stated options, not four observed results at a customer. The first option is especially sensitive. A system that can mark findings down can make a queue look healthier without fixing software. Cognition says every proposed risk adjustment requires human approval, the original Common Vulnerability Scoring System score remains visible, and entries in the known-exploited catalog are not relabeled. Those restrictions make the action reviewable. The customer still needs to know what evidence the human saw and whether the decision survived a later change to the environment.
The second option can buy time. Blocking public access to a service or inserting a web application firewall rule may reduce a known attack route before the engineering team finishes a patch. But a mitigation can fail open, cover only one interface or disappear during a later deployment. The product release explicitly says the underlying flaw stays open. A security team should preserve that distinction in its own ticket and service inventory, especially when an agent handles both the recommendation and the change.
The third and fourth options ask the most of a coding agent. A unit test can pass while a security boundary fails under another account, input or deployment configuration. Reproducing the attack before writing a fix is valuable because it creates a concrete condition to retest. Existing tests can catch unrelated breakage. Neither step alone proves a fix safe in production. That proof needs the right exploit model, a reviewer who understands the boundary, and a deployment record tied to the code version that passed.
The repair queue also changes who holds the risk. Each response moves it between people and systems. A false-positive decision leaves code in place; a network mitigation changes access; a patch changes a service; a refactor changes an architecture. The fact that all four can start in the same interface does not make them interchangeable.
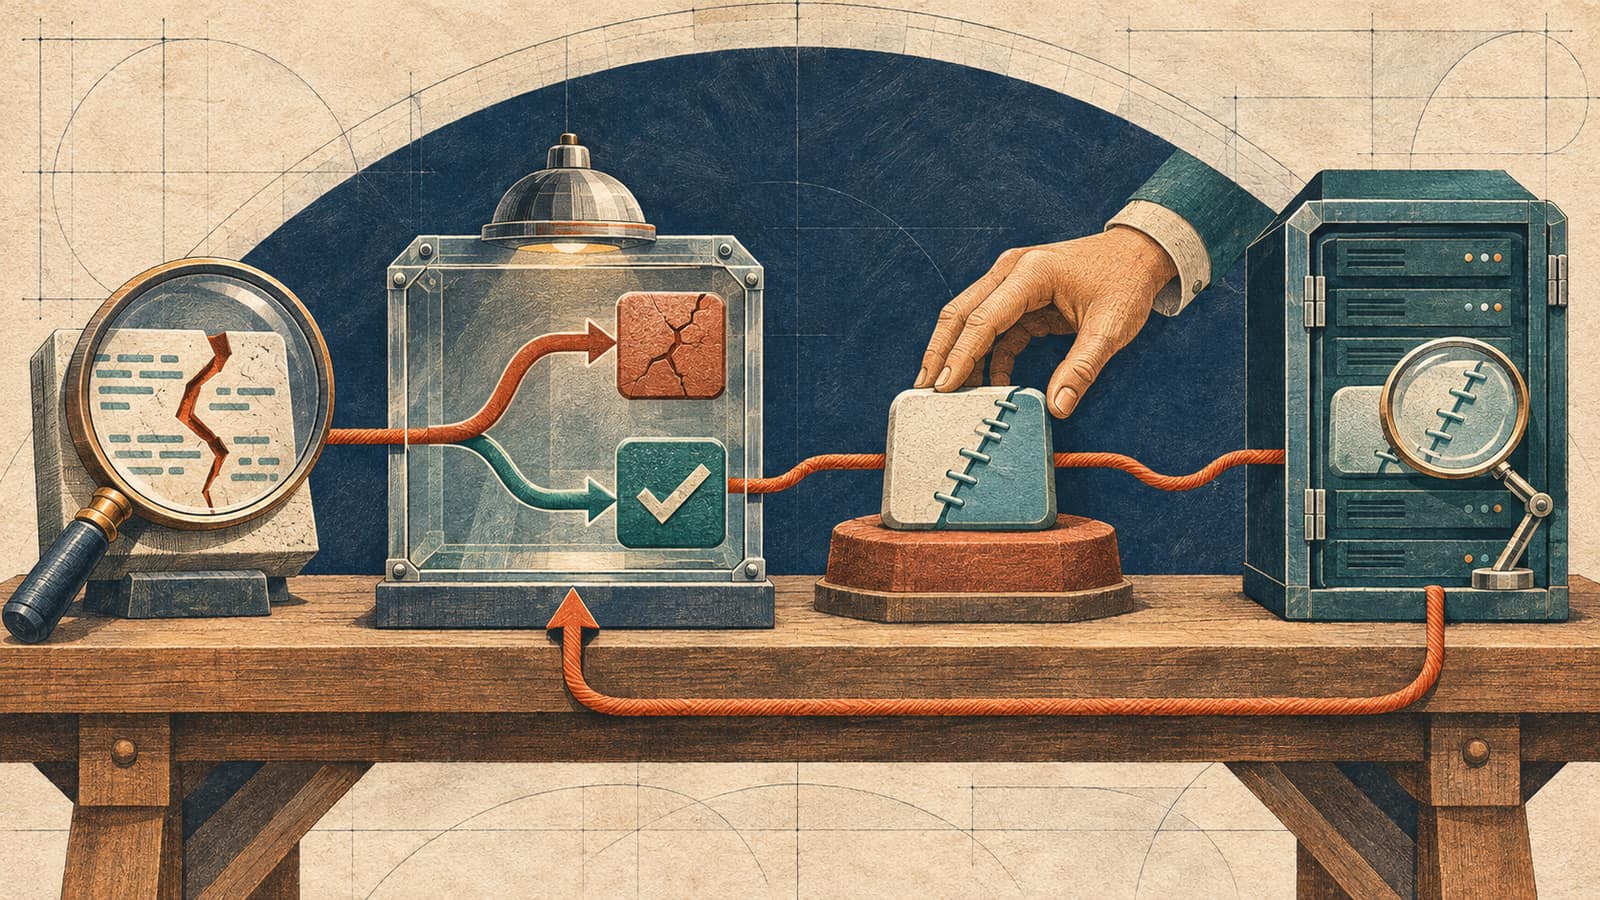
AI-generated editorial illustration. The sequence shows why a proposed patch still needs review, deployment and a later test.
Parallel agents do not remove the last reviewer
Cognition says its cloud agents can run thousands of scans and fixes in separate virtual machines. Each session can reproduce a problem, make a change and test it independently. Parallelism is useful when a team faces many unrelated repositories. It is less persuasive when the bottleneck is a shared database, a fragile deployment process or one small group of people authorized to approve high-risk changes. A thousand proposed patches can still wait behind the same production release gate. For an urgent flaw, that queue is part of the security outcome: a tested patch that waits a week behind a release freeze leaves the exposed version in service for another week.
There is a simple way to expose the difference. Track five dates for each finding: when it was first verified, when the affected owner received it, when a mitigation blocked the path, when a permanent fix reached production, and when a later check confirmed the flaw had not returned. A product can improve one interval while leaving the others untouched. Cognition’s public release gives no distribution of those intervals, no denominator for customers enrolled and no independent comparison with the same teams before adoption. Those missing measures leave an important comparison open. A buyer cannot infer a shorter exposure window from the number of running agents, even if the agents reproduce bugs accurately and write sound patches.
Independent research on coding agents gives a reason to ask for the last two dates. An empirical study of agent-written GitHub pull requests, revised in September, found that security-related changes were a minority of the public sample and received more cautious human review than other agent work. Its replication package describes those changes as often involving tests, documentation, configuration and error handling, not only direct vulnerability fixes. This sample covers public projects and multiple tools; it is not a controlled trial of Devin Security in enterprises. It does show why a merged PR count is a weak substitute for a measured security outcome.
Another study following 6,774 merged agent pull requests into later fixes starts from a related concern: accepted code may still need repair after merge. Its cohort spans several coding agents and popular public repositories, and the researchers compared it with contemporaneous human PRs. The evidence cannot tell Cognition what a bank’s production network looks like. It can tell an editor what question to ask when a vendor says its agent opened a PR. Who owned the change after merge, and did anyone test the actual service again?
Stamos has argued in his Atlantic interview that the cost of using the strongest cyber models everywhere would be too high. Cognition’s approach mixes models inside a managed workflow and offers credits for scans and remediation. The price of a scan is only one part of the customer’s cost. Someone must provide access and a current map of the system; reviewers must check the agent’s evidence; operators must schedule the release and know how to roll back a bad patch. A cheap scan that sends expensive or unsafe work downstream may worsen the queue it was meant to clear. AI can reduce some of that work. Without a measured end-to-end cohort, the share it reduces remains a claim to test.
Corridor brings another security team into the room
Cable and Ramaswami’s October 28 note says they built Corridor as a security layer for teams developing software with AI. Joining Cognition gives their group access to a larger coding-agent platform and gives Cognition more security specialists. The founders say they expect to work again with Stamos. Earlier in 2026, he had a security-product role at Corridor; Axios later reported his move to Cognition. This sequence supports a professional link among the people. It does not reveal the terms of the deal, how their systems will be integrated or whether customers have already benefited.
The integration question is concrete. Cognition’s October release offers vulnerability discovery, ranking and remediation. A security specialist arriving from Corridor may bring different detection methods, customer workflows or review habits. None can simply be assumed to appear inside Devin Security because a team joined the company. A buyer should look for a dated release, an explanation of the specific change and a way to compare results before and after. Until then, Corridor is a staffing and strategy signal.
Stamos’s own public record suggests why he would be interested in a repair workflow. Stanford’s biography describes his early work founding iSEC Partners, then leading security at Yahoo and Facebook. At each scale, the hard problem was not merely naming a technical flaw. A company had to allocate people, coordinate a response and explain risk outside a security team. At Stanford he later founded the Internet Observatory, applying research and public reporting to harms that could not be fixed by changing one line of code. These facts are institutional history, not proof that a new agent product works.
His move to Cognition narrows the test again. The product promises to connect information that often sits in separate teams: a scanner’s finding, an engineer’s code, a security analyst’s threat model and an operator’s deployment record. That is a plausible use for agents because the work crosses tools and often repeats. It is also a dangerous place for an agent to overclaim. If it cannot see a production exception or an old service path, it may write a convincing explanation for a risk decision based on a false map.
The October release therefore deserves credit for saying a human must approve a risk adjustment and for keeping a known exploited finding from being relabeled. Those rules do not answer who reviews a code change, who can deploy an infrastructure mitigation or what evidence convinces a customer that a fix is durable. A staffing announcement cannot answer those questions either. They require records from the workflow the new team is building.
The attacker story needs its own evidence
In The Atlantic interview, Stamos said AI has lifted attackers’ ability to chain steps that once required specialist labor. He described a period in which defenders discover and patch flaws while attackers race to exploit them before the patched software reaches users. The underlying risk is intelligible. A model that helps a defender inspect code can also help another actor read a public patch and search for similar weaknesses. His conclusion that defenders need to rewrite more unsafe code is a strategic judgment drawn from that risk.
Readers should separate that judgment from three different kinds of observation. A disclosed vulnerability is a flaw reported to the public. An exploit is a way to use it. A confirmed intrusion is an observed event in which someone used a path against a real system. The number of reports in a busy month cannot be substituted for the number of AI-caused intrusions. Nor does the existence of an AI-assisted discovery prove that a defender could have installed a fix any faster. Stamos himself pushed back when his Atlantic interviewer raised a claim that the internet might collapse; he said that description was hyperbole.
That distinction matters when reading Cognition’s product pitch. The release argues that defenders have less time to respond as AI improves attackers’ search, and it offers credits to help enterprises scan and fix more code. The public product post does not publish an independently audited series of attack rates, a customer-level remediation trial or a cost-per-durable-fix figure. Those are different claims. The first may motivate urgency; the latter two would test whether Cognition reduces the exposure that urgency creates.
A recent Check Point Research account offers a narrower example of the problem. TechRadar’s edited reporting describes researchers finding a way around a ChatGPT protection through an HTML preview’s popup behavior, followed by a fix that OpenAI told the researchers it had deployed. The reported bypass concerns the surrounding application. It does not show an AI agent autonomously exploiting the internet. Its relevance is that safety can fail in a connector, browser frame or deployment detail even when a model restriction appears strong. A security agent that inspects only one layer may miss the route that matters.
Security staff must decide which of many plausible reports deserves an emergency release. A customer executive may see a dramatic AI-security headline and demand that every scanner alert be fixed tonight. A careful security chief has to ask what is exposed, what is already blocked and which fix can be tested safely. Stamos’s current work will be judged in that ordinary triage room, not by the most alarming single example from a podcast.
A test a customer can actually run
Cognition could make its claim easier to assess without revealing a customer’s code. It could report, for a defined cohort, how many findings entered Devin Security, how many were reproduced, how many were judged false positives, how many received temporary mitigation, how many became reviewed PRs, and how many fixes reached production. It could publish the median and long tail from verified finding to deployed repair, plus the share reopened after a later test. The cohort would need a start and end date, the customer’s selection criteria, and a comparison that accounts for different severity and codebases. No such public cohort appears in the October 26 announcement.
These measurements would not be a simple leaderboard. A product that reports fewer findings may have missed real flaws or may have removed noise. A product that opens more PRs may have created work or shortened it. A lower vulnerability count could result from a real fix, an inaccurate risk adjustment, a temporarily hidden service or a change in what the scanner can see. The sequence of evidence matters more than the final number. A customer should ask for a sample record that shows each decision and the person or system that authorized it.
For a high-risk finding, a useful record would preserve the exact affected version, the reproduction condition, the proposed change, test results, human review, deployment identifier and post-deployment retest. It would distinguish a firewall mitigation from a code fix and keep a risk acceptance visible if the customer chose to leave the flaw open. Cognition’s release says some of these artifacts can be exported to governance tools. It does not demonstrate their completeness across a real customer cohort.
The company also needs to show how it prevents its own automation from increasing the risk. Devin Security can, with configured access, suggest or apply a network change. An agent with too much privilege could touch a service outside the intended scope. An agent with too little information might propose a patch that passes a local test but fails in production. Those are possible failure modes, not reported Cognition incidents. They make access limits, independent review and rollback evidence part of the buying decision.
A customer does not have to wait for a perfect randomized trial before using a tool on a real backlog. Many organizations already let known flaws sit because their security teams cannot hire enough engineers to repair them. A product that produces a reviewable fix for even a subset could improve their position, especially if it helps them prioritize a known exploited path. Stamos’s affordability argument speaks to those teams. It should be evaluated against their actual queue and staff hours, not dismissed because no software product can guarantee safety.
A buyer can run a more useful comparison. Take a customer’s backlog at a fixed date. Record how many verified, reachable flaws are open, how long the oldest critical ones have waited and how many engineer-hours the team spends getting a sound fix into production. Run the new workflow with explicit human approvals and compare the same measures after deployment, including reopened findings and outages. If the backlog falls because the fixes last, Cognition has evidence for its claim. If alerts disappear because classifications changed while exposure remains, it has a cleaner dashboard and the same problem.
Stamos’s published warning gives Cognition an unusually demanding standard. He says the window between finding a bug and exploiting it is shrinking. His product must make the interval between finding a bug and safely repairing it shrink faster. The next credible proof will be a customer record in which a verified flaw, a reviewed patch and a production retest can all be followed to the same version of the same service. Cognition has not yet published the customer data needed to calculate that interval.