Proton Cancels AI Staff Interviews but Keeps Its Coding Overhaul
On this page 6 sections
AI-generated editorial illustration.
An email to some Proton employees set out an unusual calendar for the first half of November. Between November 4 and 11, selected workers would be interviewed about how they used artificial intelligence in their jobs. Their interviewer would come from outside their team. They were asked to bring concrete examples, not a list of tools. The email called the exercise “consequential” and said its assessments could inform changes in roles, responsibilities and continued employment. Proton later published the text of that email in a public reply.
The wider November interviews never took place. On October 30, CEO Andy Yen said the company was canceling them and that no one would lose a job because of that exercise. More than 40 senior leaders had already been interviewed, according to the original email. Two days later, CTO Bart Butler published the engineering manifesto he had sent internally about a month earlier. He still wanted engineers to direct models, redesign workflows and reduce dependence on manual code writing.
The cancellation changed the assessment, while the intended direction of work remained. Employees need to know how the AI mandate will affect performance reviews and whether they can challenge a risky change. Customers pay Proton to protect mail, passwords, files and connections. They need to know how a faster engineering process protects those products. Proton has promised to publish its AI policies and describe its code and security reviews. As of this article’s November 8 review of accessible company material, those promised details are still a future test of the pledge.
The interviews Proton withdrew
The sequence begins with a staff email, not a completed round of employee evaluations. 404 Media reported on October 26 that it had obtained the message. Proton then reproduced its text under an official team account. The email said Yen had already interviewed more than 40 senior leaders across Engineering and Product. It proposed expanding the assessment, with invitations prioritized by the organization’s needs. An invitation, it cautioned, should not itself be read as an individual outcome. Yet it also connected the documented assessment to a broader review that could affect employment.
Those clauses sit awkwardly together. A worker told to explain what changed in their work, what failed and what they would do differently would have reason to treat the meeting as a performance assessment. The company also described it as a way to identify future leaders and support people who needed help. The email does not provide a rubric showing how a candid account of a failed AI experiment would be scored against a polished success story.
The proposed interviewer was to be outside the worker’s reporting line and chosen from leaders judged to have strong AI capability. That might reduce a manager’s local bias. It could also make the evaluator less familiar with the worker’s actual system, customer constraints or security obligations. The email did not publish a method for reconciling that tradeoff. Nor did it explain what evidence would count when an engineer chose not to use an AI tool because a task involved sensitive data or an unsafe access path.
Proton’s public comment responding to the first report said it was actively hiring and was not using AI as a pretext for layoffs. It said the exercise sought thoughtful choices about when to use AI and when not to. That is a different formulation from counting generated lines. But a promise about intent cannot erase the wording employees received. The email explicitly tied the planned assessment to possible employment changes.
After further reporting, 404 Media said on October 30 that Yen had canceled the wider re-interviews, citing six current employees and audio of an all-hands meeting it obtained. Yen’s own public statement confirmed the reversal. The original reporting also described staff concerns about security and leadership conduct. Those accounts are reported allegations, not an independent finding by this publication. Proton disputes the suggestion that it has traded away security.
The cancellation settles a narrow question: the specified November 4 to 11 program will not proceed. Yen did not abandon AI-assisted engineering or say that ordinary performance reviews would stop. The CTO’s memo published afterward still calls for a broad redesign of engineering work.
A manifesto for a different engineering job
Butler’s November 1 publication is unusually explicit about what the company wants. It says an engineer’s job is no longer chiefly to write code; the engineer should help a language model write better code, steer agents, fix repeated failures and create context that others can reuse. The memo describes individual use of AI to speed existing tasks as “phase 1” and calls for a second phase that changes the workflow itself. It names CI capacity, design, approvals, specifications and code review as possible new bottlenecks.
This is a management proposal, not evidence that Proton has already achieved its promised gains. Butler says that the company often does not know where its bottlenecks lie because it has not invested in tools to find them. He also says wider redesign requires organizational resources, not only individual engineers experimenting at their desks. That admission gives the memo a more concrete question than whether employees are enthusiastic enough: which shared systems will Proton fund, and who will be responsible when they fail?
Butler casts the engineer as a small team leader. A model may propose an implementation while a human supplies architecture and judgment. He argues that documentation and tests remain important; their economics may change if writing tests gets cheaper. He also writes that most human code review may eventually end. The timetable is unclear. A tool can produce tests more cheaply today. Whether a privacy product can rely on machine review for a sensitive change is a separate claim. It needs a product-specific control and a measured result.
Butler explicitly warns readers that his memo is not an in-depth document about security, reliability or infrastructure. That caveat is useful. The manifesto says where management wants engineers to go; it does not show the route a change to Proton Mail or Proton Pass takes through review, penetration testing and release. It cannot answer the customer’s security question on its own.
There is a practical reason for the company to push beyond autocomplete. A developer can ask an agent to draft a patch, then spend longer waiting for an environment, an approval or a test suite than the tool saved in typing time. In an April 2026 survey of 1,528 DevSecOps professionals, commissioned by GitLab and conducted by Harris Poll, 85% agreed that AI had moved the bottleneck from writing code to reviewing and validating it. 79% said individual productivity had improved without the whole delivery process accelerating at the same rate. These are survey responses across firms, not measurements of Proton’s engineering performance.
The memo therefore identifies a real class of organizational problem, even if its most sweeping predictions about manual coding and human review remain unproven at Proton. An employer can ask teams to improve the workflow. It still has to specify how an engineer should report a model’s unsafe output, and how a reviewer can slow a release without being marked as resistant to change.
Evidence from another coding tool helps clarify the role change without pretending it measures Proton. Anthropic studied about 400,000 Claude Code sessions from October 2025 through April 2026. Its classifier attributed roughly 70% of planning decisions to users and 80% of execution decisions to Claude in a typical session. That division makes Butler’s picture of an engineer directing an agent plausible as a description of some work. The same study found that expertise at the task changed how effectively people used the agent. Anthropic’s measurements come from its own tool and its own classifier; they do not establish that every Proton engineer can delegate the same work safely.
There is an uncomfortable training problem inside the proposal. If the experienced engineer’s value increasingly lies in recognizing a bad design, a younger colleague still needs chances to learn what a sound design looks like. Delegating all routine implementation can remove a place where that judgment used to be built. Butler says expertise remains valuable, but the memo does not specify how Proton will teach it if the shape of entry-level engineering changes. A company can train workers on agent tools and still owe them access to the architecture, incident history and review discussions that make a good prompt possible. The job may become more demanding before it becomes easier.
Privacy customers set a harder standard
Proton’s product promise gives this dispute a consequence beyond office policy. Its October 15 product roadmap describes encrypted mail, storage, passwords and a planned Lumo API. Proton says the API will let developers bring its assistant into their own workflows with the privacy protections of the Lumo app. Its Lumo privacy documentation says chat data is not logged or used to train models without specified consent and describes encrypted storage. These are company claims about product design, not an independent audit of the development process.
For a customer choosing a privacy service, software quality is part of the purchase. A defect in a consumer photo app may be annoying. A defect in an encryption or account-recovery flow can change who can access sensitive data. More generated code can still be useful, but speed has to be judged against the severity and reversibility of mistakes. A security team purchasing Proton for an organization may ask for a threat model, review path and incident response even if it welcomes faster product releases.
Yen’s October 30 statement addresses that concern directly. He says AI use will never come at the expense of security, that Proton does not install software to count AI-generated code on employees’ laptops, and that the company added layers of security review over the past year. He says the company uses AI to find vulnerabilities too. These are Proton’s assertions. The statement does not provide a dated inventory of added controls or comparative findings from before and after the changes.
Yen also promises a more testable answer. Proton will publish where AI is and is not allowed, explain its code and security review processes, and open source some internal tools. Those commitments could let a buyer compare the company policy with a real release path. Publishing source code already lets others inspect a product’s final form, but it reveals less about the decisions that produced a change: who reviewed it, which tests ran, what the agent could access and why a risky diff was accepted.
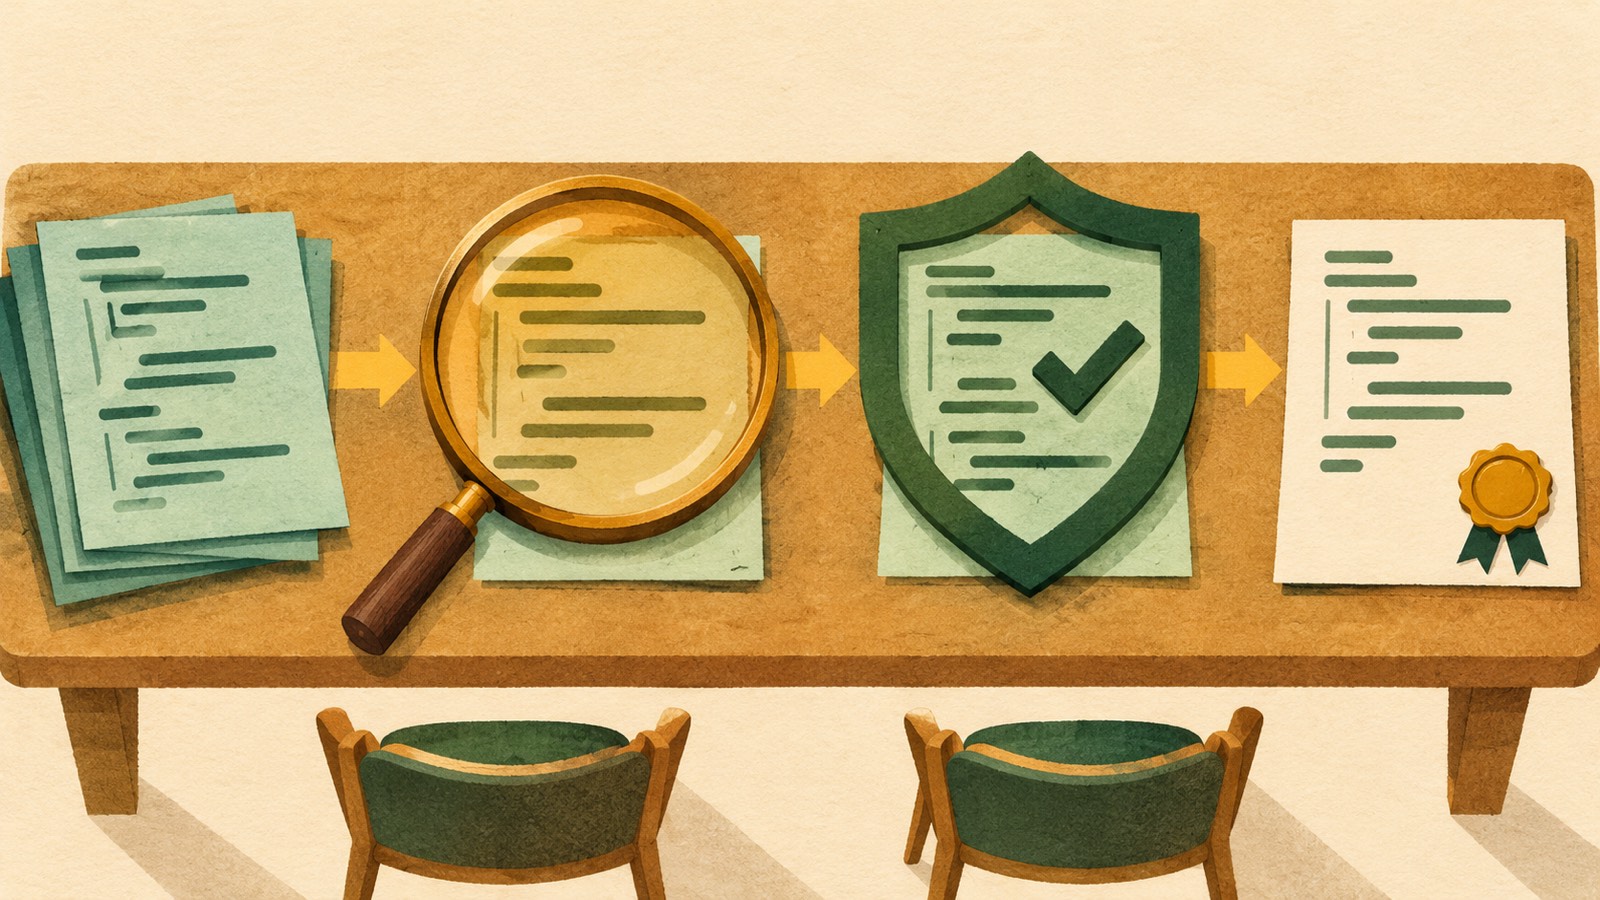
AI-generated editorial illustration. The stages represent review questions, not Proton’s documented workflow.
If Proton cuts release time, a customer still has to trust the code that arrives at the end of it. Saying that AI and security can coexist does not show what happened in the pipeline. The company has promised to make that process visible.
Consider an illustrative scenario, not a reported Proton release or incident. An agent proposes a change to an account-recovery flow. The diff passes unit tests, but its fallback path would let a user bypass a second check under a rare error condition. A reviewer who understands the threat model catches the gap; a generated test that only follows the happy path does not. The important public question is not whether the first draft came from a model. It is whether Proton’s process assigns someone the time and authority to inspect that path before deployment. The scenario would apply to any security-sensitive software maker. Nothing in the accessible public record says this specific defect occurred at Proton.
NIST’s Secure Software Development Framework gives buyers and suppliers a shared vocabulary for practices that reduce vulnerabilities and address root causes. It does not prescribe a single AI-tool policy or certify Proton. Its relevance here is the level at which a buyer should ask questions: security requirements, development practice, verification and response to discovered problems. A company could satisfy those practices with AI in parts of its workflow; a company could also fail them while insisting that humans wrote every line. The process and evidence decide, not the tool label.
Employees describe two different realities
Public employee comments show why it would be a mistake to treat every worker as holding one view. A Reddit user identifying himself as Richard, a long-serving Proton staff engineer, posted a defense of the company after the investigation. He said a tool that labels AI-generated code was not designed to measure individual usage. He also argued that a security discussion had been quoted without its full context: in his account, Yen supported additional penetration testing while resisting delays in the pipeline. He described a move toward “Product Engineering,” with engineers expected to exercise product judgment rather than only write code.
In the comments on that post, a user identifying herself as Dani, Proton’s lead for Docs and Sheets, described a different experience. She wrote that the AI direction might be right but the proposed interview process had been handled poorly, and that she had challenged Yen internally. She said colleagues had thanked her because they were afraid to speak. These accounts are self-identified public statements. Their employment and the private conversations have not been independently verified here. They nonetheless set out distinct positions in the same public discussion: disagreement over leadership conduct can coexist with support for learning to use AI.
For a security team, silence has a cost. If a worker believes that naming a flaw in AI-generated code will be taken as resistance to management’s plan, a warning may never reach the reviewer. If every concern is treated as a reason to avoid AI entirely, the company can miss tools that reduce repetitive work or catch vulnerabilities. An evaluation process should reward the person who finds a failure early, even when the discovery slows a release.
A manager can count AI-tool launches. The count says a tool was opened, nothing about the resulting change. Generated-line totals can reward verbose code. A demo can reward a polished success while hiding unresolved failure cases. The original Proton email asked workers to discuss what had not worked, a better prompt than a tool count. The employment language around that request made candid failure reporting more costly for the worker.
The public record cannot establish what every Proton employee experienced or how all managers now evaluate them. It can establish that a formal cross-team assessment was announced, that its possible employment consequences were written down, and that the company reversed it. The remaining question for staff is whether the ordinary performance process will distinguish good judgment from visible AI enthusiasm. Proton has not published the evaluation method needed to answer that question.
The different employee accounts also create a specific management test. Richard’s post says the company is moving toward product engineers who exercise judgment. Dani’s comment says workers can support the AI direction while fearing how leadership handles dissent. Those statements do not need to be collapsed into a vote for or against the technology. If product judgment is a job requirement, an engineer must be able to tell a senior leader that the proposed release date is unsafe, explain the evidence and expect the concern to be heard. A company cannot get that kind of judgment by asking only for more AI usage examples.
The canceled interviews would have asked people to describe failures and lessons. That could have yielded useful evidence if the process were clearly separated from employment threats and matched to each worker’s actual responsibilities. An infrastructure engineer, a product designer and a customer-support specialist have different opportunities to use AI and different risks if they use it badly. One cross-team rubric can compare behaviors such as testing assumptions and correcting mistakes, but it cannot treat a count of tools, prompts or generated lines as a common denominator for job value. Proton’s official comment said it wanted thoughtful decisions about when not to use AI. A revised assessment would need to show how that restraint earns credit.
The evidence Proton can still publish
The company’s next move can be judged against its own promises. A privacy vendor does not need to publish exploit details or expose employees’ personal records to demonstrate its process. It can describe categories, gates and accountability: which kinds of source code an agent may see; whether prompts or tool calls can leave Proton-controlled environments; whether generated changes require a named human owner; which changes require a security reviewer; what happens when a test fails; and how incidents feed back into the policy.
A published rule that every sensitive change receives security review is useful. A sample of release records showing the rule was applied, with sensitive details redacted, is stronger. A dashboard saying reviews became faster would be incomplete without defect, rollback or incident context. A buyer needs to see the path from a representative change to the checks that stood between generation and release.
CISA’s Secure by Demand guide makes software buyers part of that conversation. It asks customers to question a manufacturer’s security practices instead of accepting a generic assurance. A corporate buyer of Proton could therefore request a security-process description tied to AI use: which repositories and data an agent can access, which release classes require human review, and whether an independent security team can block a change. The buyer does not need the company’s private prompts or a list of employees. It needs enough detail to distinguish an approved tool with controls from a broad promise that speed and safety can coexist.
For the workforce, the parallel request is a readable account of how performance is judged. Does a reviewer credit an engineer for rejecting a model-generated shortcut? Can a worker report a dangerous tool behavior without turning it into a mark against their adaptability? Who can appeal an assessment when the evaluator sits outside the reporting line and lacks local context? The canceled email did not answer these questions. They remain practical because the AI overhaul continues even after the scheduled interviews were removed.
| Public claim or decision | Evidence available by November 8 | Next checkable proof |
|---|---|---|
| November AI re-interviews were canceled | Yen’s public statement and 404 Media’s meeting-based report | Whether any replacement assessment is announced, with criteria and employee safeguards |
| Engineers should use agents and redesign work | Butler’s published memo | Documented training, approved tools and a process for escalating unsafe output |
| AI will not weaken product security | Yen’s assertion of added review layers | Published AI-use boundaries, code/security review process and release evidence |
| Faster development will help customers | Product roadmap and management rationale | Measured release quality and customer-relevant outcomes over comparable periods |
This matrix separates a completed reversal, a management direction and two promises that still need corroboration. It does not presume a breach, a completed layoff, or a measured productivity gain. A customer can ask for the promised process description before treating the security pledge as verified. An employee can ask what happens to a reported failure before treating an AI-skills evaluation as fair.
AI-assisted development makes output easier to generate and harder to explain after the fact. GitLab’s survey found 43% of respondents could not reliably distinguish AI-generated from human-written code in their own codebase and 34% of organizations that had experienced an incident could not determine whether AI-generated code contributed. Survey design and self-reporting limit what those numbers prove. Proton can answer the provenance question for its own products by publishing the process it has promised.
After the cancellation, the release path still matters
The October reversal removed the scheduled November meetings from employees’ calendars. It did not resolve the management question Butler posed: how should a software company reorganize work when an engineer can delegate more code creation to models? A customer still needs an answer to a narrower question: what prevents a faster pipeline from releasing an unsafe change to a privacy product?
Both questions can be answered with observable decisions. Proton could show how it trains engineers, which tasks agents may perform, which reviewers can stop a release and what its security team has authority to require. It could publish the promised policies, then explain how a representative change passed through them. Employees could then judge whether the company values reported failures. Buyers could judge whether its security pledge has a process behind it.
For now, the most concrete artifacts remain an email announcing an assessment that never happened, a manifesto asking engineers to work differently, and a CEO statement promising to make the new process visible. The company has canceled the meeting. The work of earning confidence in the code still has to be shown.