AWS Can Bill for ChatGPT Enterprise Without Hosting All Customer Data
On this page 8 sections
AI-generated editorial illustration.
On November 9, OpenAI put ChatGPT Enterprise in AWS Marketplace. A buyer can use an existing AWS purchasing and billing relationship, and eligible spending can count toward an AWS cloud commitment. Sophos chief technology officer John Peterson described the appeal in the launch announcement: applying an existing commitment could remove procurement work that slows an enterprise rollout.
The product listing contains an unusually direct qualification. Buying through AWS Marketplace does not guarantee that all customer data stays on AWS infrastructure or inside the customer’s AWS environment. OpenAI remains the processor for ChatGPT Enterprise and uses subprocessors, including AWS, to support the service. The page also distinguishes the region where supported content is stored from the region where inference runs.
The listing changes the path of the purchase. It leaves a buyer to check the processing path separately. A procurement team could approve a private offer using an AWS account and still need to examine OpenAI’s processor terms, regional settings and the work employees plan to do. A marketplace label is too small to serve as an infrastructure map.
An AWS checkout and an OpenAI service
The launch offers access to ChatGPT, ChatGPT Work, Codex and dots under ChatGPT Enterprise. OpenAI says marketplace customers receive the same models, features and release timing as customers buying directly. Developers can also use OpenAI models in Amazon Bedrock, but that is a different product path: a model service for applications rather than a managed workspace for employees. OpenAI’s November 9 announcement makes that division explicit.
The AWS listing names OpenAI as the seller and calls the delivery method software as a service. Its purchase route is a request for a private offer, not a public one-click price. OpenAI’s own pricing page also sends enterprise buyers to sales for custom pricing. A buyer can therefore learn that a product is available before knowing the quote, the eligible portion of a cloud commitment, the precise service terms, or the final operating budget.
AWS’s private-offer documentation explains the mechanics. A seller and buyer can negotiate custom pricing and legal terms. The offer is extended to specific AWS accounts, then accepted as an agreement. An AWS account that can pay an invoice is not automatically the account that will administer an employee’s OpenAI workspace. Those are separate permissions and records that must be matched in the buyer’s internal process.
The offer needs more than a price line. AWS says a private offer can include a custom end-user license agreement, payment schedule, renewal and changes to entitlements. A buyer can see an offer only after the seller extends it to the proper linked or management account. The person negotiating commercial terms may therefore need a cloud-account owner to confirm receipt before a business unit can compare the offer with a direct OpenAI quote. The public listing does not provide that quote. The accepted offer, not the promotional page, is the record a buyer must preserve.
The cloud team may already have an agreement, a billing workflow and commitment capacity. A business unit wants access to an AI product. The marketplace connects the purchase to the existing account. The manager who requested the product still has to decide what staff will use it for, who approves access and who checks the output.
OpenAI used the same purchasing logic before the AWS listing. Its August update to an Oracle agreement says eligible Oracle Universal Credits can be used to buy OpenAI models, Codex and ChatGPT Work through Oracle Marketplace in the United States. Its October Google Cloud announcement says eligible Google Cloud commitments can be drawn down for models purchased through Google Cloud Marketplace; at publication, general availability was planned for the following weeks. These products and dates are different. The common mechanism is a pre-existing cloud spending commitment becoming a channel for AI purchases.
The commitment can make a purchase easier to approve
Cloud commitments are usually decided well before a specific team requests a new tool. That timing helps explain the appeal of the November 9 announcement. OpenAI says eligible ChatGPT Enterprise spending can count toward AWS commitments, and the listing specifies AWS Enterprise Discount Program or Private Pricing Agreement commitments, subject to a customer’s agreement. The word eligible matters. Neither page says every buyer, seat, invoice or usage category will qualify on the same terms.
The listing’s custom-price path keeps the actual economics private. A buyer should separate at least four numbers: the quoted subscription or credit commitment; the amount eligible for AWS drawdown; the team’s internal allocation of that spend; and the cost of making the tool useful. A lower barrier to signing a contract does not establish lower total cost. It can instead change which budget is visible first.
There is a second marketplace with a similar name and a different flow of money. OpenAI Marketplace lets eligible OpenAI enterprise customers apply part of an OpenAI commitment to qualifying partner products. In its initial program, OpenAI and the partner confirm eligibility, the customer contracts with the partner, the partner invoices, and OpenAI records the eligible amount against the OpenAI commitment. AWS Marketplace’s ChatGPT Enterprise offer runs in the other direction: an OpenAI product is purchased through an AWS relationship and may count toward an AWS commitment. A finance team searching for a marketplace policy must identify which program its contract actually uses.
Neither marketplace description promises automatic eligibility. The OpenAI help page says qualifying purchases depend on the customer, product and purchase. The AWS listing says eligible consumption counts toward AWS EDP or PPA subject to the customer’s agreement. The safest commercial comparison uses a dated, written eligibility answer for each proposed quote. Otherwise, a forecast can count the same expected benefit in a spreadsheet that the final contract does not provide.
Illustrative scenario, not a reported buyer meeting or customer case: a company has an AWS commitment and several departments asking for ChatGPT Enterprise. Procurement accepts a private offer through the AWS account. IT provisions the workspace. Finance assigns the charge to a cloud commitment, while managers ask employees to try Codex or ChatGPT Work. Those actions may happen in separate systems. The invoice records a transaction. It cannot count useful employee work or identify where each request was processed.
One public customer did supply a narrower statement. Sophos CTO John Peterson said in OpenAI’s announcement that buying through one channel and applying existing AWS commitments could let his company spend less time in procurement and more time using AI. It is an attributed prospective benefit, not a measured before-and-after result. The release provides no Sophos contract value, rollout count, savings figure or security audit. Those missing numbers should stay missing.
Seats are a poor measure when the offer includes interactive chat and delegated work. OpenAI’s enterprise usage report says that as of June, Codex generated 64% of combined Codex and ChatGPT output tokens among its enterprise customers. It defines a high-use group in the top 10% by output tokens per active user; that group’s volume was 8.3 times a middle group, up from 2.6 times in January. The vendor observed activity, not productivity or return on investment. A buyer may have a full seat roster and still know little about the work completed.
A bill, a workspace and a processing path
The AWS page is careful about what its label means. The listing says the service is deployed on AWS and that AWS is one of OpenAI’s subprocessors. It also says purchasing there does not guarantee that all customer data remains on AWS or within the customer’s AWS environment. Both statements can be true because a software service can use several systems, subprocessors and regional processing paths.
The buyer needs separate answers for the invoice, the workspace and the processing path:
| Buyer question | What the public pages establish | What the buyer still needs |
|---|---|---|
| Who sells and bills for access? | OpenAI is the seller; purchasing and billing run through AWS Marketplace. | The private-offer price, payer account, term, renewal and internal chargeback. |
| Who controls the employee workspace? | OpenAI describes administrative control over users, permissions and connected tools. | The organization’s actual admin roles, identity integration, seat policy and approval settings. |
| Where is customer data stored and processed? | The listing distinguishes data residency, inference residency and other processing. | A region-by-region review of the contracted options, feature coverage and subprocessor terms. |
The table describes questions a buyer can put beside a private offer. It does not describe any particular customer’s configuration. A valid bill says little about the region used for a given task.
The listing says data residency governs where supported customer content is stored at rest. Inference residency separately governs where model inference on that content runs on GPUs. It warns that these options only apply when enabled, do not cover all processing or systems data, and are unavailable in some regions. A buyer with a hard regional requirement must therefore identify the exact feature, data type and process at issue. A broad statement such as “we bought it on AWS” cannot settle those details.
OpenAI’s business data page says customer inputs and outputs from Enterprise are not used to train its models by default. That is an important privacy commitment, but it answers a different question from storage and inference location. A company can require both a no-training default and a specific processing region. It must confirm each separately in the applicable terms and settings.
Residency has a feature boundary
OpenAI’s residency guidance makes the geography more concrete. As of November 10, 2026, it lists ten storage-at-rest regions for eligible ChatGPT Enterprise and Education customers, from Australia and Canada through Europe, the United Kingdom and the United States. Inference residency is listed for three regions: Europe, the United States and the United Arab Emirates. An eligible customer needs data residency enabled in the same region before inference residency applies. These are product settings and eligibility conditions, not automatic consequences of buying through an AWS account.
The guidance tells workspace administrators where to check the configured setting: Workspace settings, then General, then the data and inference residency fields. Those fields show the current configuration; they are not controls for changing it. A buyer who needs a specific region should have an administrator verify the workspace and the account team confirm eligibility before treating an offer as complete. It is possible to know the cloud commitment is eligible for drawdown and still lack the setting needed for a data requirement.
The feature list is just as important as the region list. The guidance describes conversations, files, custom GPTs, memory, image inputs and outputs, and data-analysis artifacts as in-scope content for storage. It says new features are not covered until listed. The same page identifies Codex Web among unsupported features, while the Codex app and command-line interface are supported. A buyer asking engineers to use Codex therefore needs to specify which surface they will use. The name of a product family does not answer whether a particular workflow is within a residency promise.
External connections create another boundary. OpenAI says information sent to an app, MCP server or web browsing provider is handled under that provider’s own storage and processing terms. Its inference-residency commitment covers GPU execution on in-scope content in supported regions; CPU-based extraction, routing and coordination may still occur elsewhere. The buyer’s data diagram should start with an actual task, such as reading a contract or reviewing a code repository, and follow each enabled connection. A region setting on the main workspace is one part of that diagram.
The October 14 subprocessor list gives a second check. It names AWS, Microsoft, CoreWeave, Oracle and Google Cloud among infrastructure subprocessors for ChatGPT Enterprise, alongside providers for other functions. The list does not say that every customer request touches every named provider. It does show why an AWS procurement route cannot be treated as an exclusive infrastructure promise. The data-processing addendum describes OpenAI’s authority to use listed subprocessors and its process for notifying customers of changes. Contract review has to work from those documents and the customer’s selected options, not from the logo beside the purchase button.
Illustrative workflow, not a reported customer case or observed product test: a lawyer puts a document into a chat, then asks an approved app to search an internal drive. The chat and the app may operate under different processing terms. OpenAI’s public documentation supports that distinction; the actual path depends on the buyer’s settings. Staff need a plain list of approved connections and the data each may receive.
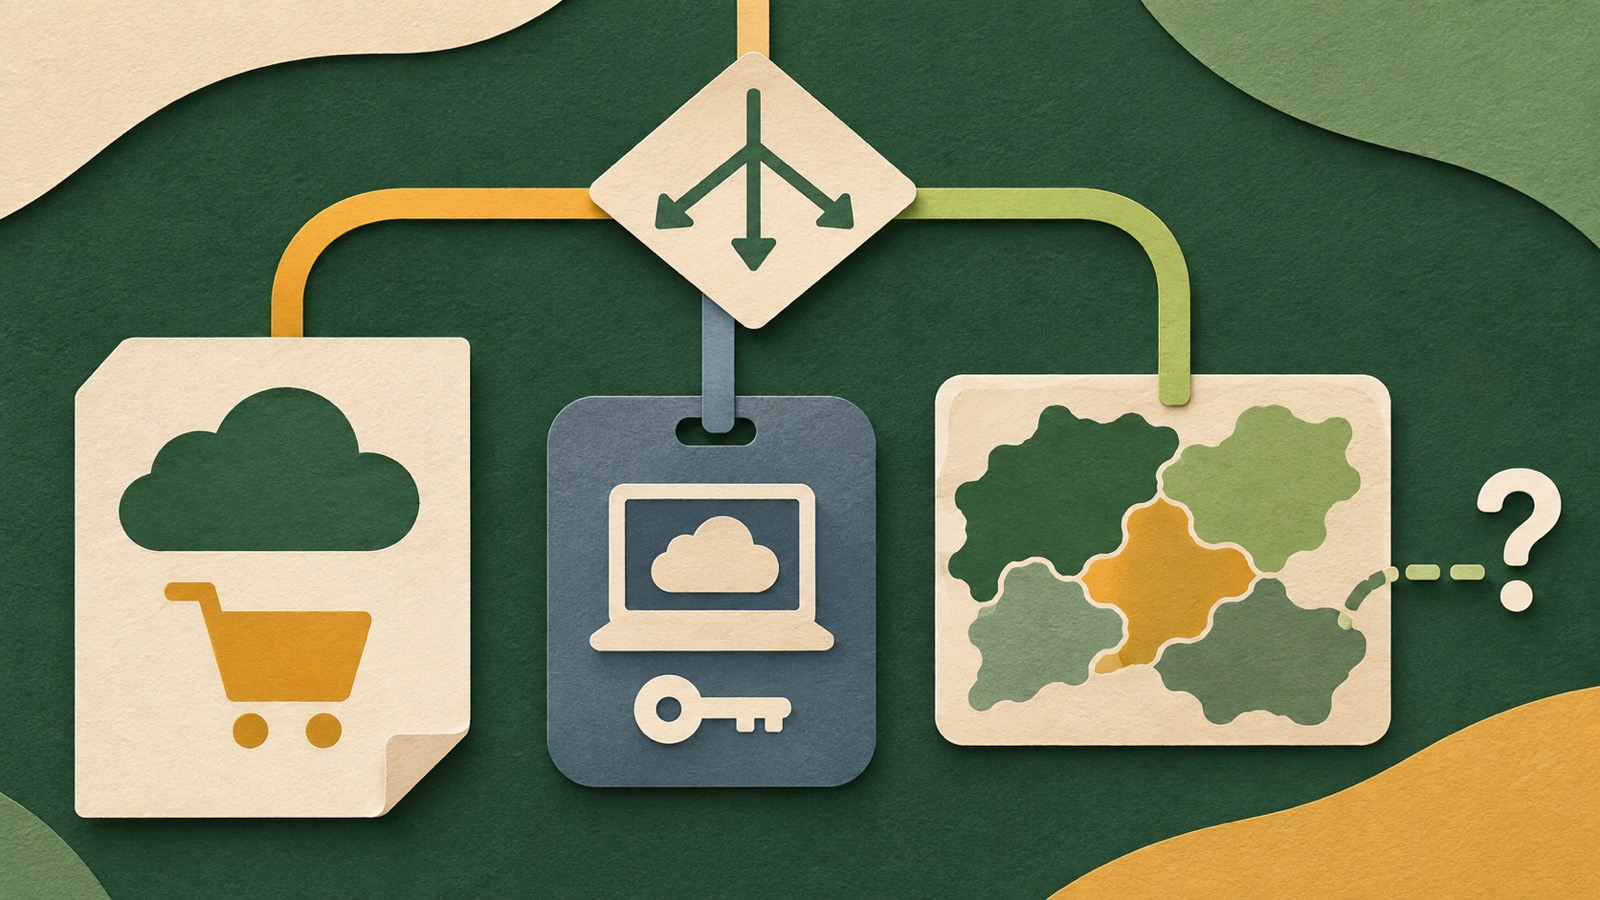
AI-generated editorial illustration. The cards separate the purchase route from the service and data-location decision.
Microsoft remains in the picture
The AWS sale sits inside a larger cloud arrangement. In April, OpenAI and Microsoft announced an amended partnership. OpenAI said Microsoft remained its primary cloud partner and that its products would ship first on Azure unless Microsoft could not and chose not to support the necessary capabilities. The same statement said OpenAI could serve all its products to customers across any cloud provider. Microsoft’s license to OpenAI intellectual property runs through 2032 under the announced terms and is no longer exclusive.
That agreement makes the AWS route less surprising than it might have seemed under earlier exclusivity language. It does not tell a buyer which infrastructure serves every feature of a particular ChatGPT Enterprise contract. The marketplace listing is the more direct source for that buyer question, and it expressly limits the inference one can draw from the purchase channel.
The contrast with Bedrock is useful. A developer buying a particular model service in Bedrock is choosing a deployment and API path with its own region, billing and access documentation. A company buying ChatGPT Enterprise in AWS Marketplace is purchasing a managed software product with its own workspace, processor and contractual controls. OpenAI calls the offerings complementary in its launch note. Treating them as interchangeable would erase the work needed to choose the product that fits the task.
The Google and Oracle arrangements have different product boundaries. The Google Cloud plan concerned models in Model Garden and a future availability window. The Oracle update covered several OpenAI products and specified US availability. The AWS launch makes ChatGPT Enterprise available now. All three can route eligible spending through a cloud commitment, but they do not deliver the same product on the same date.
A buyer can compare products inside the same marketplace
The AWS page for ChatGPT Enterprise itself points to Claude Enterprise as a similar product. That listing says Anthropic’s enterprise assistant can also draw down AWS EDP or PPA commitments. It describes Claude Chat, Claude Code and Cowork as a single enterprise offer and invites a private-offer request. The two pages are vendor descriptions; neither page supplies a neutral comparison of task quality, quoted prices or data-location guarantees for a specific customer.
This matters because a commitment is sometimes presented as the constraint that selects the vendor. The public listings show at least two assistant products that can use the same broad purchase channel. If both are eligible for a company’s agreement, the AWS route does not settle which product a team should use. A fair pilot would give the same task, input boundaries and reviewer standard to each candidate, then record output quality, review time and total usage cost. The private offers would still need separate contract reviews.
The comparison should also distinguish a workspace from an API model. A developer team may want Bedrock’s model-access route for software it builds. A legal or operations team may want a managed assistant with shared administration. Some firms will need both. The November 9 listing broadens the procurement options for the managed assistant; it does not collapse these different needs into one budget line.
Workspace controls become part of the budget story
Buying an enterprise license may be the shortest part of an enterprise AI rollout. Administrators still need to decide who gets access, what connected tools employees can use, which agent actions require approval and how usage is measured. The AWS listing says administrators can manage user access, permissions and connected tools, while users remain in control of what agents can access and which actions require approval. The public page does not show how any buyer configured those controls.
OpenAI added credit usage analytics and updated spend controls in June. It said administrators could break down ChatGPT and Codex credit consumption by user, product and model, inspect trends in a Global Admin Console, and use a unified Cost API. The company also described default workspace limits, group limits and individual overrides. Those features can help a finance team see where credits go. They cannot by themselves say whether the output saved staff time, improved a decision or caused a mistake.
Group and individual limits shape the work people can finish. A low default keeps a trial cheap but may interrupt a longer delegated task. A generous one can hide a growing bill when no one examines the output. OpenAI says employees can see their credit use, request more, and include the work context for an administrator’s decision. An operator could use that request to name the task and a reviewer, then record whether the result was accepted. OpenAI describes the controls; it does not report that customers use this review method or that it improves outcomes.
The user analytics also need a denominator. A department with ten active people will show different patterns from one with a thousand provisioned seats. An increase in output tokens may reflect longer agent tasks, a model change or more users; it is not a direct measure of employee time saved. OpenAI itself calls token output a proxy for depth of use in its August report. A buyer can ask for active users, task type and reviewed result alongside spend, then compare the same unit over time. Without that work record, a dashboard can tell finance where a cost appeared while leaving managers unable to explain what changed.
The distinction matters as use spreads beyond software engineering. OpenAI’s August enterprise report says weekly active Codex users since February grew 108 times in legal, 41 times in sales, 41 times in recruiting and 26 times in marketing, compared with five times in engineering. These are growth multiples from different starting points and are measured within OpenAI’s customer base. They do not establish that legal, sales or recruiting jobs were eliminated, that each firm gained the same value, or that the reported activity is representative of all enterprises.
The report also finds a difference by seniority. Six months after an organization adopted the product, early-career employees in its sample sent 13 more messages per week than executives. That is usage, not a verdict on which group needs the tool most. It does complicate a rollout built around senior sponsors and a small number of executive licenses. The worker who experiments with a daily task may make more use of a seat than the person who signed the budget. A manager deciding who gets access needs evidence from actual work, not a job title.
That employee view is absent from the AWS listing, as it should be: a sales page cannot know a buyer’s tasks. The gap has a budget consequence. Provisioning hundreds of seats before naming the work can produce a large committed purchase with little guidance for the people who receive it. Restricting all advanced use to a few specialists can miss useful workflows elsewhere. A staged rollout can record what employees attempted, where a reviewer intervened and which work was worth repeating. That record gives finance a reason to renew, change or stop a contract when the first term ends.
For an operator, the practical measurement unit is a completed task with a reviewer and a cost. A coding agent that opens a pull request, a research agent that prepares a source file and an employee who drafts a memo all consume access differently. A purchase program can standardize the invoice. It cannot make those outputs equivalent. Finance needs a trace from the private offer to workspace spend; managers need a trace from the workspace to useful, checked work.
A cloud commitment can make one product easier to fund. An employee team might find another product more useful for a particular task, while IT wants fewer systems to administer. The offer does not resolve that disagreement. Record the task and the reason for choosing a tool before the available budget becomes the explanation.
The contract review after the announcement
The public AWS listing gives a buyer enough information to start a focused review. It does not publish a universal enterprise price, a customer-specific eligibility result, a complete data-flow diagram or a demonstrated return on investment. OpenAI directs buyers to account teams to confirm eligibility. AWS asks them to request a private offer. Those are concrete next steps, but the offer itself is where a buyer can test the claims against its own requirements.
A useful review has four files. First, the commercial file: private-offer price, term, payment schedule, eligible AWS commitment treatment and renewal. Second, the product file: which ChatGPT Enterprise features and seat or credit types the company intends to use. Third, the data file: the processing addendum, subprocessors, residency options and exclusions for each planned workflow. Fourth, the work file: a small set of tasks, named owners, reviewer time, usage cost and an explicit measure of useful output. These are proposed buyer questions drawn from the cited terms, not a claim about a particular company’s purchasing policy.
The files should be versioned together. AWS private offers can be amended, and OpenAI’s subprocessor list and feature guidance can change. A quote evaluated against one data-processing description could be accepted after another appears. Recording the document date, the chosen workspace settings and the owner who checked them gives a later renewal team a way to reconstruct the decision. It also tells employees which restrictions came from a contract and which came from an internal choice. A purchase that is easy to place on the cloud bill still requires someone to maintain that account of the work.
The first three files prevent a category error. An AWS invoice cannot answer an OpenAI admin question. A no-training promise cannot locate every inference call. An available private offer cannot prove that employees will change their work. The fourth file tests whether the subscription becomes more than an accounting entry.
OpenAI has a reason to make purchasing easy, and AWS has a reason to make committed spending useful to customers. Buyers also have a reason to welcome a familiar channel. The November 9 launch aligns those incentives at the checkout. The unresolved decision sits one step later: when the private offer arrives, someone must place the invoice beside the processor terms and the actual employee workflow, and sign only the set of answers the company can defend.